
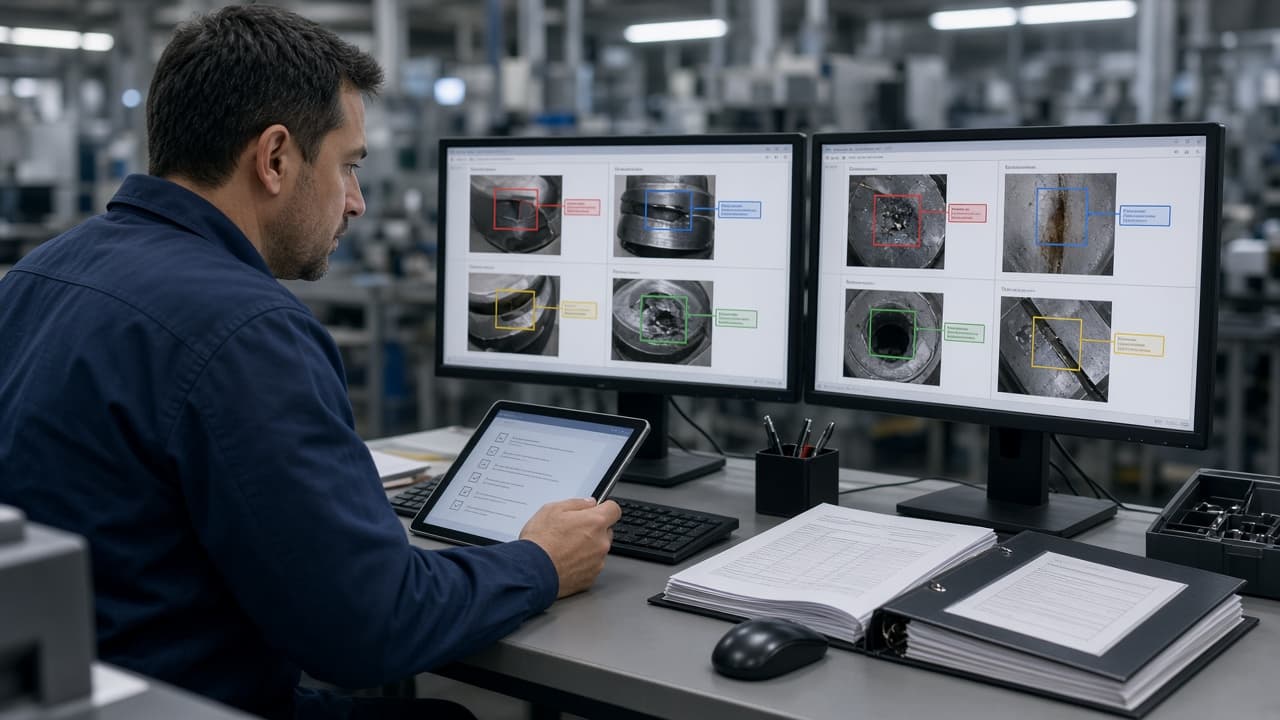
Quality publishes Rev D of the scratch/dent dictionary on Tuesday. Annotators keep labeling against the Rev B PDF pinned above the station. The model that ships on Friday inherits a plant that no longer exists on paper. False rejects climb on the new “cosmetic accept” band; escapes hide in the class that used to be scrap. Nobody changed the network weights on purpose. The labels stopped matching the controlled procedure.
Agreement metrics catch disagreement between people under one guideline. Label-noise essays catch wrong tags inside a frozen dictionary. Threshold MoC catches cutoff edits on the HMI. This brief is the quieter failure: SOP revision without label-set rebinding.
A useful rule is boring and enforceable. Every training or gold image carries the SOP revision ID that governed its labels. A new revision does not automatically obsolete the archive—but it does freeze promotion of any model whose training mix includes obsolete codes for classes that changed meaning. Images that still apply keep their old revision stamp; images that need rework go through a queued relabel under the new text, not a silent “keep tagging.”
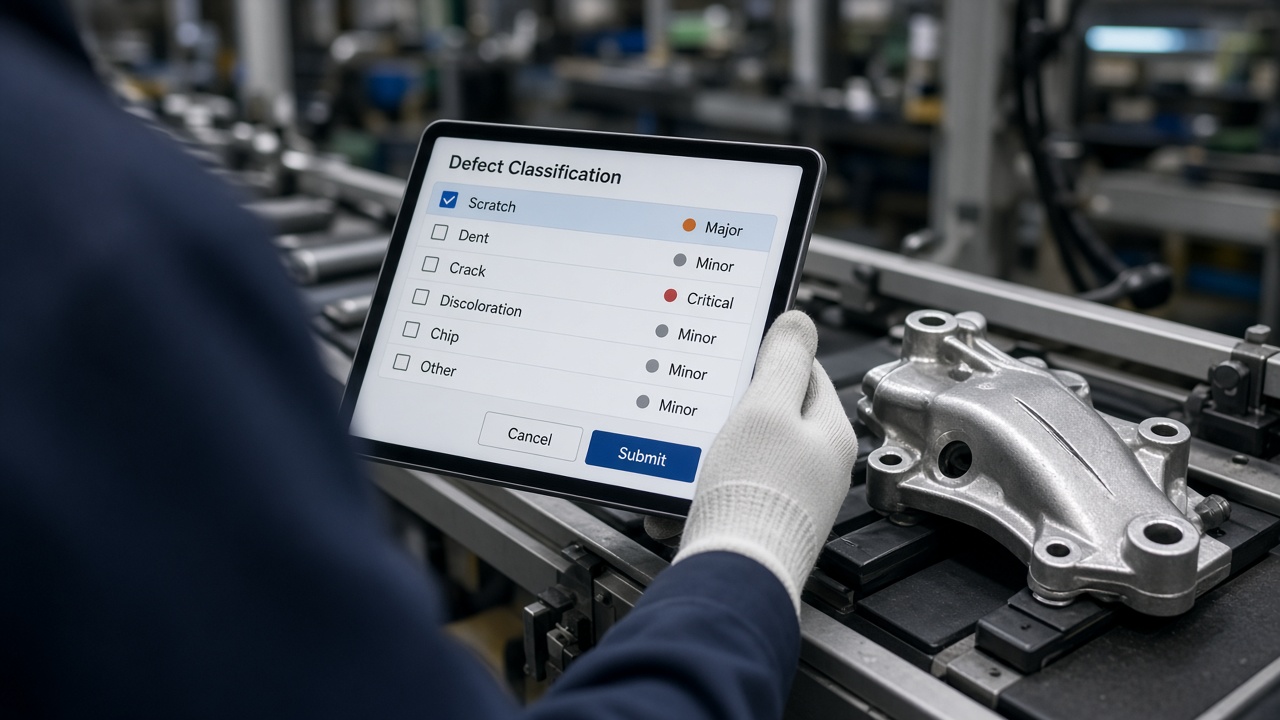
Floor practice that survives audits looks like this: the active guideline on the tablet matches document control; the labeling tool refuses save without a revision field; champion promotion checks that the dataset’s SOP set is a subset of currently effective revisions for those defect codes. If Rev D reclassified hairline marks from reject to accept, any gold set still teaching “reject” is sabotage wearing a PNG.
Retrain after the relabel, not before. Measuring κ on a mixed Rev B/Rev D cohort is measuring two plants at once. Sites that treat guideline revision as a data event—same seriousness as a recipe MoC—stop wondering why last month’s champion looks confused after a “documentation only” update.