
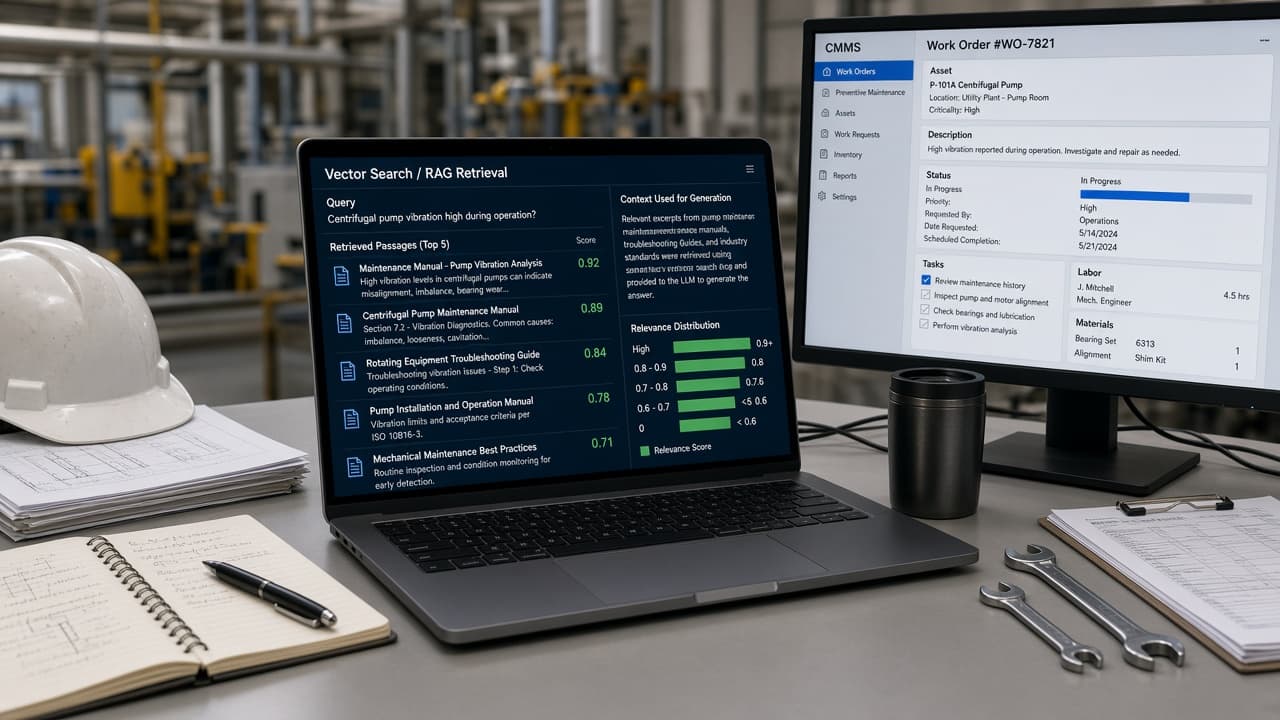
Plants that wire a retrieval-augmented assistant into CMMS or shift handover expect the system to surface the right procedure for the asset tag on the screen. What usually breaks is not “the LLM forgot maintenance.” It is the vector index: an embedding model upgrade, a chunker change, or a half-updated PDF corpus that leaves old vectors pointing at new filenames—or new vectors that no longer sit near the old ones.
Concept drift on plant features and champion–challenger promotion are adjacent topics. This note is embedding and index honesty for maintenance RAG.
Failure modes that look like bad answers
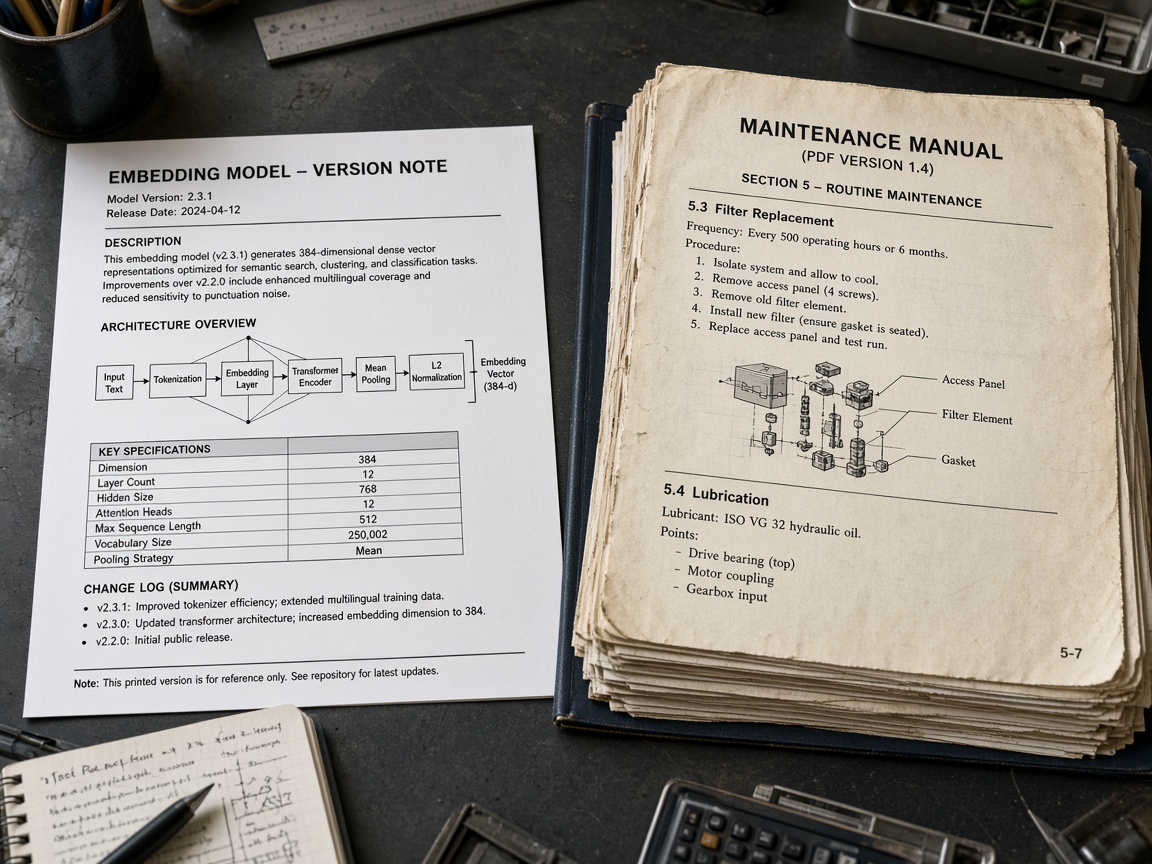
- Model swap without re-embed. A new embedding checkpoint changes geometry; old vectors and new queries live in different spaces. Top-k looks confident and wrong.
- Corpus edit without reindex. A revised SOP PDF replaces the file on disk while chunks still cite the previous revision hash.
- Chunking change. Heading-aware chunking replaced by fixed token windows after a library bump—section titles no longer anchor retrieval.
- Mixed multilingual manuals. One embedding model under-serves KR/TR PDFs while EN chunks dominate neighbors.
What to freeze and what to reindex
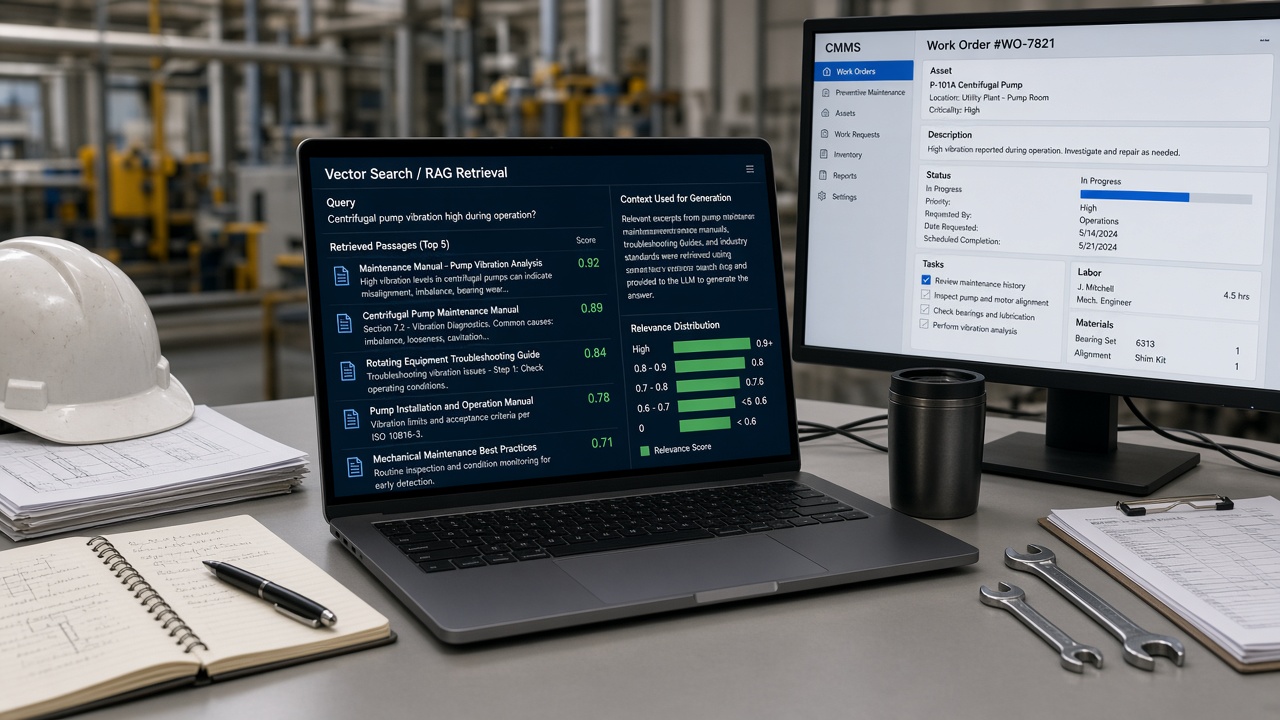
Treat embedding model ID, chunker version, and corpus snapshot ID as a single deployable. Promote them together. After any change, rebuild the index and run a golden query set: known asset IDs, failure codes, and LOTO procedure titles with expected document IDs. Score hit rate before exposing the assistant to the floor.
Guardrails that belong next to retrieval
Cite document ID and revision in every answer. Refuse when similarity falls below a threshold. Never let free-text retrieval alone authorize a work order write—CMMS tool calls still need allowlists.
A maintenance copilot that “used to find the right SOP” usually lost its index geometry, not its manners. Rebuild the vectors before you blame the generator.