
Launch week for a new product family is when plants most want automated quality scoring—and when historical models are least entitled to it. Features may look familiar. Defect modes, lighting on the new tooling, and the cost of a false reject usually are not.
Concept drift explains slow world change. Champion–challenger and canary rollouts explain how to promote a ready model. This note is the gap before either applies: cold-start quality models for new SKUs—what you do when labeled history is thin or zero.
A cold-start plan that survives contact with the line usually includes:
- Eligibility rules. The old champion does not auto-score the new family until a gate says so. Default is human inspection or a conservative rule set, not a borrowed neural net.
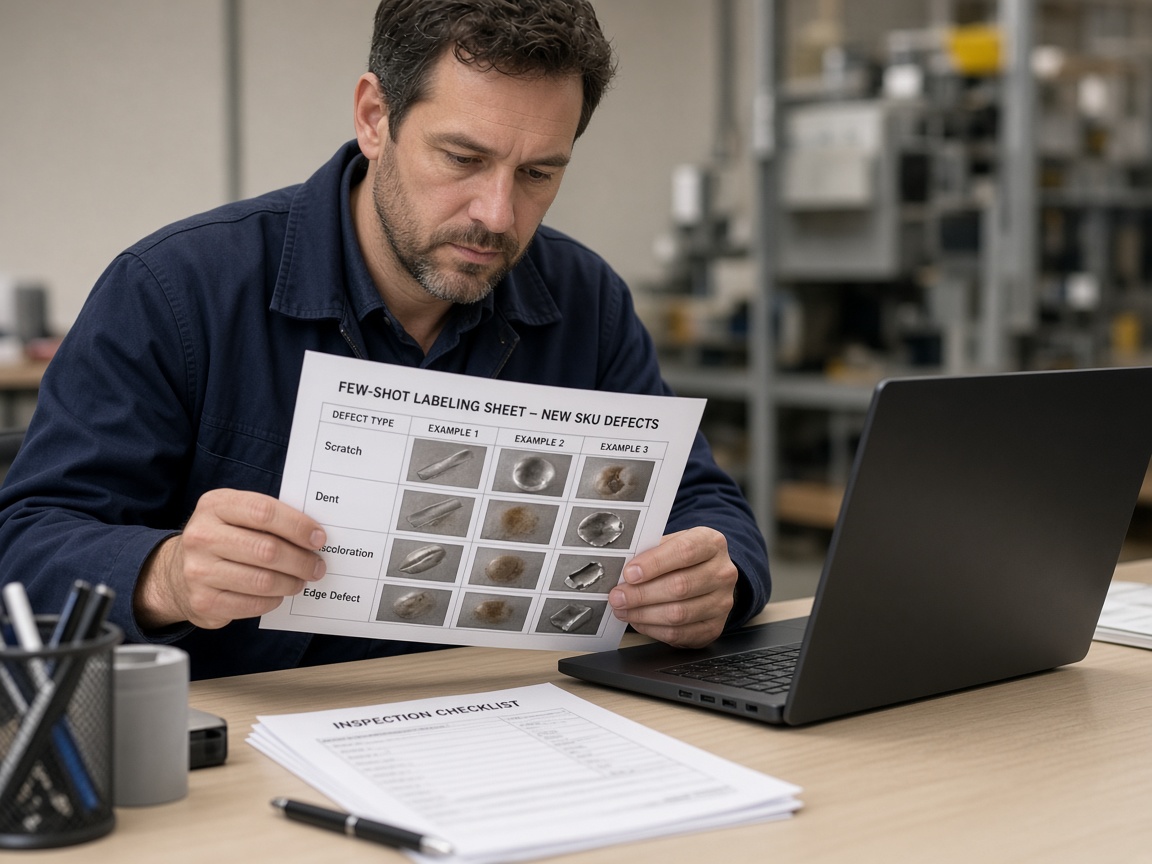
- Few-shot labeling with owners. A fixed daily sample of the new SKU gets ground truth from named inspectors, not from “whoever had time.” Label definitions are written before the first score goes live.
- Shadow only until evidence. Any candidate model logs scores without driving rejects. Compare disagreement clusters and escape proxies against human disposition—not against the old champion’s opinion of a SKU it never saw.
- Promotion criteria on paper. Minimum labeled count, maximum false-reject lift on the sample, and a kill switch back to human-only. Skip the hopeful cutover.
Synthetic data and transfer learning can shorten the wait. They do not replace a disposition rule for week one. Plants that bolt a new SKU onto last year’s boundary buy quiet scrap and loud arguments about “the AI.” Plants that freeze eligibility, label on purpose, and shadow until a gate clears launch the model after the product—not instead of inspecting it.